TCP
TCP, the Transmission Control Protocol, has a primary role of adding reliability to the unreliable lower layers. There are a lot of moving parts to it, and a lot of subtle details.
The full data transfer is broken up into smaller units called segments. In most internet communication, these segments won't exceed 1500 bytes. This limit is due to Ethernet (at the Data Link layer), which has a limitation of 1500 bytes of data. Some of the 1500 bytes is taken up by TCP and IP headers, so typically, the data in a TCP is not more than 1460 bytes. The limiting size is called the maximum segment size or MSS.
Reliability is achieved by assigning each segment a sequence number. As we'll see, sequence numbers are used to help each side know what data has and hasn't arrived and to help keep things in order since sometimes packets can take different routes through the internet and hence take varying amounts of time to arrive. We will start with how a TCP connection is established.
3-way handshake
We will refer to the two parties establishing the connection as client and server. Things start off with a passive open, which is where someone starts up a program on the server and tells it to listen for traffic at a specific port number. When the client wants to connect, they send a message to the server. This is called an active open. That first message contains a few things. The first is that the SYN flag in the TCP header is set to true. Here, SYN is short for “synchronize sequence numbers”. In addition to setting the SYN flag, the client also lets the server know what its initial sequence number is. For reasons we'll talk about later, the initial sequence number is not usually 0 or 1.
The server then sends a TCP message with the SYN and ACK flags set, along with its own initial sequence number. In TCP, each side can send data to the other, and each uses separate sequence numbers for their own data. ACK is short for “acknowledgment”. The ACK is the server acknowledging that it got the client's first message. The last part of the handshake is an ACK from the client, acknowledging that they got the message from the server. Now the connection is established, and data transfer can start.
Just remember it as three parts: (1) SYN, (2) SYN-ACK, (3) ACK. It's possible to mathematically prove that a 3-way handshake of this sort is needed in order for both sides to be confident that they are connected. For instance, if we omit the final ACK, there would be no way for the server to be sure if the client is receiving what it sends. As we'll see later, there's a little more that happens in the 3-way handshake, namely that each side can exchange information about their window size and certain TCP options.
Closing a connection
Closing a connection is somewhat similar to the 3-way handshake. Closing starts when one side decides it is done sending data. It sends a message with the FIN (finish) flag set. The ACK flag will also be set (it's actually set in every TCP message except in the initial SYN of a 3-way handshake and a few other rare situations). The other side will send back an ACK to acknowledge receipt. Then it will notify the application layer process that is using the connection, telling it that the other side wants to close the connection. This gives the process time to finish what it is doing. When it's done, the process notifies TCP and then a FIN-ACK is sent to the other side. That side sends one last ACK, and then the connection is closed.
Well, it's almost closed. There is usually a delay of a couple of minutes before reusing the same connection. If the same connection is reused too soon, it's possible that late-arriving packets from the previous connection could cause some confusion in the new connection.
How TCP achieves reliability
Below is a picture of 5000 bytes of data, broken into five segments of 1000 bytes each.

Each segment is given a sequence number, which is the number of the first byte of the segment. For example, we have the following based on the picture above:
Segment 1 contains bytes 0 to 999. Its sequence number is 0.
Segment 2 contains bytes 1000 to 1999. Its sequence number is 1000.
Segment 3 contains bytes 2000 to 2999. Its sequence number is 2000.
Segment 4 contains bytes 3000 to 3999. Its sequence number is 3000.
Segment 5 contains bytes 4000 to 4999. Its sequence number is 4000.
Sequence numbers make it easy to put segments in the right order when they don't arrive in order. They also give a way to see which segments get lost.
When a receiver gets data, they send acknowledgements (ACKs) back to let the sender know they got the data. An acknowledgement is indicated by setting the ACK flag to true and by supplying an acknowledgement number. That acknowledgement number is the number of the next byte the receiver is expecting. This is a little subtle, and it takes a little time to understand the consequences. In particular, if a receiver sends an acknowledgement number of 3000, that means that they have received all the bytes from 0 to 2999 and the next one they are expecting to get is byte #3000. ACKs are sometimes said to be cumulative in that an ACK automatically acknowledges every segment that came before it. Here are a few scenarios using the figure above. The sender and receiver are called Alice and Bob.
- Suppose Alice sends Segment 1 to Bob. It has sequence number 0 and contains bytes 0 to 999. Bob sends an ACK with acknowledgement number 1000 to acknowledge getting Segment 1. The number 1000 tells Alice that Bob has received bytes 0 to 999 of the overall transmission and is expecting to get byte 1000 next.
- Suppose Alice sends Segment 2 to Bob. It has sequence number 1000 and contains bytes 1000 to 1999. Bob sends an ACK with acknowledgement number 2000 to acknowledge getting Segment 2. The number 2000 tells Alice that Bob has received bytes 0 to 1999 of the overall transmission and is expecting to get byte 2000 next.
- Suppose Alice sends Segments 1, 2, and 3 to Bob. Though Bob could send ACKs for each one separately, he can also send just a single ACK with number 3000. Since ACKs are cumulative, this is Bob telling Alice that he has received all the bytes from 0 to 2999 and the next byte he is expecting is 3000. Most TCP implementations use this idea and don't send ACKs for every segment, but instead often just send one for every two segments.
- Suppose Alice sends Segments 1, 2, 3, 4, but 3 is lost in transmission. Even though Bob got Segment 4, he can't send an ACK for that. The ACK number for it would be 4000, which would be telling Alice that he got bytes 0-3999, which isn't the case. The best Bob can do is to send an ACK with number 2000, indicating that he got the first two segments.
A sender has a few ways to recognize that a segment is lost.
- Timeout: If an acknowledgement doesn't come back after a certain amount of time, then the sender assumes the segment was lost and resends it. How long should the sender wait? On most TCP implementations, the sender will typically wait at least a few hundred milliseconds, and potentially longer if the connection is slow or highly variable.
The sender times packet transfers and keeps a running average of how long round trips take to the receiver and back. The timeout length is then the larger of two values: a “floor” that is typically a few hundred milliseconds and a value based on the average round trip time and how much it varies. The timeout length keeps doubling if timeouts keep happening, up to a maximum of typically around 2 minutes. After enough time with no response, the sender will give up on the connection.
- Triple Duplicate ACK — The initial TCP specification had timeouts as the only way to detect packet loss. A TCP sender will typically fire off segment after segment, since sending things one at a time, waiting for an ACK to arrive before sending the next would be very slow.
Suppose the sender sends segments 1, 2, 3, 4, and 5, and 2 is lost. First, the receiver ACKs the first segment. Then the receiver can help let the sender know that 2 has been lost by sending repeated ACKs for segment 1 when they get segments 3, 4, and 5. The three later ACKs are called a triple duplicate ACK. When the sender gets all those duplicate ACKs, they recognize that the receiver is trying to signal to them that they are missing a segment, and they resend it. This happens much more quickly than waiting for a timeout, so it is called a fast retransmit.
You might wonder why we wait for three duplicates and not just send things after a single duplicate. It's fairly common for two segments to arrive out of order, which would generate a single duplicate ACK but no lost segment. So we don't want to do a fast retransmit in that case because there was no lost segment. It would be a waste of bandwidth, and it also has a negative effect on the congestion window size (see later). However, three duplicate ACKs due to segment reordering is much less likely since that would mean several segments were all out of order.
- RACK-TLP — For many years, triple duplicate ACKs were the main way of detecting segment loss without waiting for a timeout. However, with faster networks and changes at the lower layers, packets could be seriously out of order, leading to triple duplicate ACKs that were due to packet reordering, not packet loss. Triple duplicate ACKs also don't work if the loss happens with one of the last couple of segments. They also don't work well if the retransmission itself was lost.
The new solution, RACK-TLP (Recent Acknowledgment - Tail Loss Probe), was adopted in the early 2020s. It relies on a TCP option called SACK (Selective Acknowledgment). See later for more on TCP options. SACK allows a receiver to specify a few ranges of bytes to help indicate which ones it has. The sender can infer based on that if there is something still missing. If SACK indicates a segment is missing, the sender will wait a short amount of tim—a few round trip times, which is enough time so that they can assume the missing segment wasn't due to a simple reordering—and then resends it. This is much quicker than waiting for a timeout.
The TLP part of it is for missing segments at the end of a group of data segments. There won't be any later ACKs for a while to help indicate that the segment went missing, so the sender sends a “probe” segment to elicit an ACK. The probe typically contains new data if there is any, or else it will be the most recent data segment it sent.
An example of TCP data flow
Suppose Alice and Bob are in the middle of a TCP connection. Bob has already sent bytes 0 through 11999 to Alice, and Alice has already sent bytes 0 to 999 to Bob. Remember that each has their own set of data they are sending to the other, so Alice's data and sequence numbers are separate from Bob's. Let's say the next several steps are shown below.
- Alice sends bytes 1000–1499 to Bob.
- Bob sends bytes 12000–12999 to Alice.
- Alice sends bytes 1500–1999 to Bob.
- Bob sends bytes 13000–13999 to Alice.
- Bob sends bytes 14000–14999 to Alice.
- Alice ACKs Bob's recent transmissions but has no new data to send.
- Bob sends bytes 15000–15999 to Alice.
- Bob sends bytes 16000–16999 to Alice.
- Alice ACKs Bob's recent transmissions but has no new data to send.
Here is what the sequence and ACK numbers would look like. Alice's data is indicated in red to help you keep things separate.
In the first step, Alice sends bytes 1000–1499. The sequence number always matches the first byte of the data, so it's 1000. The ACK number is the next byte Alice is expecting from Bob. This is 12000 since we said that Bob already sent bytes 0 to 11999.
In the second step, Bob sends bytes (from his data) 12000–12999. The sequence number is 12000 (first byte of the data), and since he just got Alice's 1000–1499, he sends an ACK with the next number after that, which is 1500.
Skipping down a bit, notice that Alice's ACKs at Steps 6 and 9 have a sequence number of 2000, even though Alice doesn't send any new data. If someone is sending an ACK without new data, the sequence number is the next byte they would send if they did have data. Similarly, Bob's ACKs from Step 4 on are 2000. This is because Alice doesn't send any more new data after Step 3. So the next byte Bob is expecting stays at 2000.
Below is a screenshot from Wireshark showing a real data transfer when I downloaded a web page.

The first three segments are the handshake. Next comes the HTTP request that I made. That was 494 bytes, with 440 bytes of it being data and the rest being the headers from Layers 2 to 4. That was the last time I sent data to the server. Notice that all the remaining segments from me (port 3079) to the server (port 80) all have sequence number 441. This is me sending ACKs to the server. All of the server's ACK numbers are 441, indicating that the next byte they are expecting from me would be 441.
Notice also that the server's sequence numbers are mostly going up by 1460 (from 1 to 1461 to 2921 to 4381, etc.). They are sending me 1460 bytes of data. The 1514 in the length field indicates the total packet size including headers.
Flow control
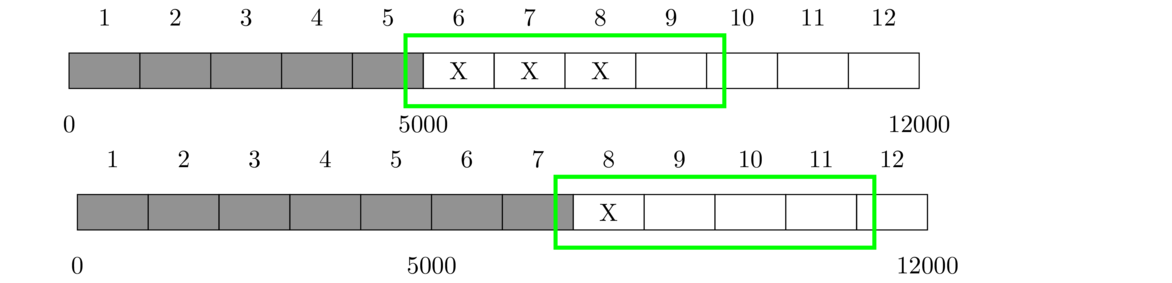
Besides reliability, TCP also provides flow control, which is a way for a receiver to keep from being overwhelmed by data from a sender. It allows the receiver some control on how fast the sender sends data to it. This is achieved via something called the sliding window. It is shown in the figure below.

The figure shows a 12,000-byte data transfer, broken into 12 segments of 1000 bytes each. The gray shaded cells indicate segments that have been sent and ACKed. The cells marked with an X indicate data that has been sent, but not yet ACKed. The unshaded cells indicate data that hasn't yet been sent. The green box around a group of cells indicates the sliding window.
In the top figure, the sliding window is 4000 bytes in size, currently starting at byte 5000, encompassing Segments 6 to 9. That 4000-byte window indicates the range in which the sender is allowed to send data. Currently, they have used up 3000 of the 4000 bytes. They are only allowed to send 1000 bytes more.
Let's suppose that the sender gets an ACK with number 7000 indicating that Segments 6 and 7 were received. This frees up 2000 bytes in the window, and the whole window slides 2 segments (2000 bytes) to the right. Now, 3000 bytes of the 4000-byte window are okay to send, specifically the data from bytes 8000 to 10999 (Segments 9, 10, and 11).
In general, the window size is defined as how much unACKed data is allowed to be in transit from the sender to the receiver. If the receiver gets bogged down processing the data being sent or if they are bogged down with other stuff, they can decrease the window size. They can also increase the window size if they can handle data at a faster rate. Every TCP message has a window size entry in the header, where the receiver can specify their window size. Window sizes typically range from a few kilobytes up through a few megabytes on ordinary internet connections.
A related problem is sometimes programs like SSH send keypresses over the network one at a time, which means we end up with really inefficient packet sizes, this time due to something on the sender side.
The solution on the receiving side is called Clark's solution. Roughly speaking, it says that instead of advertising really small window sizes, the receiver should wait until it can advertise something reasonable, like a full MSS-sized segment or a decent-sized portion of its buffer. On the sender side, the solution is called Nagle's algorithm. In it, if they have sent data and haven't yet gotten an ACK back for it, they can't send any more small segments until they get an ACK back or until they have enough to send a full-sized segment. If they are not waiting for an ACK, then they are free to send a small segment. Nagle's algorithm doesn't work so well with highly interactive programs, like games, so those often need to disable it for their connections.
TCP Congestion Control
Congestion in a network is similar to congestion on roads and highways. It happens when there is a lot of network traffic, with packets taking longer than usual to arrive or possibly getting dropped entirely.
In the 1980s, a phenomenon called congestion collapse happened to the internet. Speeds dropped from 32,000 bits per second all the way down to 40 bits per second. The reason for this has to do with how TCP deals with lost and slowly arriving packets. Suppose we start with a network that is pretty busy. This means packets arrive slowly or possibly not at all. This causes timeouts, which means TCP senders will resend the lost packets. This adds more traffic to the network, slowing it down even further. This, of course, triggers more retransmissions, which slows things down further still. This vicious cycle continues until network speeds slow to a crawl.
People had to come up with a solution to this. We will cover the simplest solution here. Over the years, this solution has been modified somewhat, but the basic idea is still the same. The original version was called TCP Tahoe. The version that was used for a long time is TCP Reno. Many modern systems use improvements we will look at later. We will look at a simplified version of TCP Reno here.
In all systems, the sender maintains a window called the congestion window that is a limit of how much stuff they are allowed to send (specifically how much unACKed data they are allowed to have in transit). This is a separate window from the flow control window.
Here is how things will evolve:
- Initially, the limit is 1. The sender sends a segment, gets an ACK back, and the limit increases to 2.
- Now that the limit is 2, they send 2 segments. If everything is okay, they get back 2 ACKs, which increases their limit by 2. So the limit is now 2+2 = 4.
- The limit is now 4, and they send 4 segments. If things are still fine, they will get back 4 ACKs, which increases their limit by 4 to 4+4 = 8.
- The limit is 8, they send 8 segments, get back 8 ACKs, and increase their limit to 8+8 = 16.
From here, we can see what happens: The limit increases exponentially as 1, 2, 4, 8, 16, 32, 64, …, doubling every time. Of course, this can't continue forever. After 20 steps, we would be at a limit of over 1 million segments. So at some point, this has to stop.
- If a segment loss is detected by a triple duplicate ACK or with RACK-TLP, it is considered the less serious of the two types of losses. In this case, we cut the slow start threshold to half the current window size, decrease the congestion window to that value, and do congestion avoidance (so the limit/window size increases by 1 full segment each round trip).
- If the segment loss is detected by a timeout, this is the more serious type of loss. It is a stronger indication that the network is congested, so the response is more severe. The slow start threshold is cut to half the current window size, like before. But now we drop the congestion window all the way back to its initial value (1 in our simple example) and go back to the slow start phase.
Below is a graph showing what this all looks like. The x-axis is time and the y-axis is the number of (full-sized) segments. The dots shown in red indicate packet losses. Slow start thresholds are shown with dashed lines. Assume the slow start threshold is initially at 16.

We start out at a limit of 1 and go through the exponential doubling process until we get to the slow start threshold of 16 segments. At that point, we switch over to congestion avoidance, which is where the limit increases by 1 with each round trip time. At time 13, we lose a segment, with the loss detected by a triple duplicate ACK. So we drop the limit down to half the current window, which is 12, and that is our new slow start threshold. The next loss, also detected by a triple duplicate ACK happens at time 24. We cut in half again, this time to a limit and slow start threshold of 11 and resume congestion avoidance. The next loss, at time 34, is detected by a timeout. This is the more severe type of loss, so we drop down to a limit of 1 and proceed to increase by 1. The slow start threshold is also set back to half the window size, which is 10. The exponential doubling of slow start continues until we reach the slow start threshold of 10, and then we switch to congestion avoidance and increase by 1 each round trip.
The exponential doubling in the slow start phase very quickly increases the window size, so calling it “slow start” is a bit misleading. We can't double forever, so we eventually switch to the more conservative approach of increasing the window by 1 full segment per round-trip time. This is the congestion avoidance phase. The increase by 1 segment is called additive increase, and the cutting in half of the threshold and sometimes the window is called multiplicative decrease. The additive increase/multiplicative decrease idea is used elsewhere in networking and in situations that involve sharing a limited resource.
The algorithm is always pushing the boundary, trying to find what the network's limit really is. When we lose a segment, we treat that as meaning we have pushed the network too far, and we back off. A loss detected by a triple duplicate ACK is considered a small hiccup since later ACKs were able to get to us. A loss detected by a timeout indicates a potential for more severe network congestion, so we pay a more serious penalty. The amount of congestion on a network can vary over the course of a connection, and this algorithm will be able to adjust to those changes.
The algorithm described above is a somewhat simplified version of the classic TCP Reno algorithm. For instance, in real systems, the congestion window is often started at 10 segments. Modern systems can also use RACK-TLP to detect segment loss, and the congestion control algorithm treats that similar to how it treats triple duplicate ACKs.
In TCP there are two windows: the congestion window and the flow-control sliding window. The congestion window is about protecting the network from congestion. The flow-control sliding window is about protecting a receiver from being overwhelmed with incoming data. Overall, a sender must look at both window sizes and never send more data than is allowed by either. For instance, if the congestion window size is 4000 bytes and the sliding window is 7000 bytes, then 4000 is the most that can be sent.
One important consequence of all of this is that starting a new connection is slow. First, there's the 3-way handshake that involves some back and forth, and then, because of slow start, it takes a few more steps before we can be sending a decent amount of data. In the original version of HTTP, each resource downloaded from a new webpage required a new TCP connection. A big speedup was realized in HTTP/1.1 where connections could be reused for multiple resources.
Google introduced their own algorithm called TCP BBR that they use on their servers. The algorithms we covered use segment loss as an indicator of network congestion. BBR takes a different approach: it measures how quickly packets are being delivered, it measures the round trip time, and uses those to build a model for how congested the network is.
The TCP header
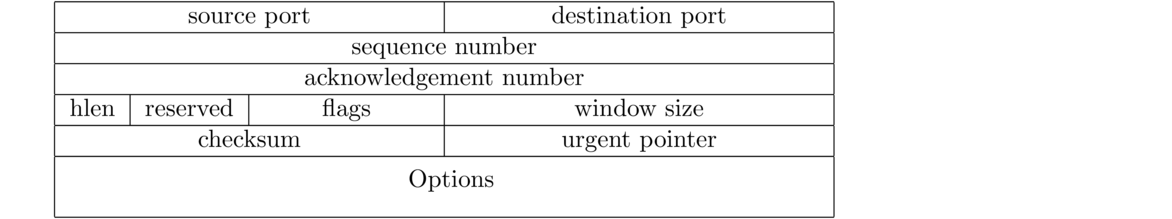
Below is a diagram of the TCP header. This is the “envelope” that goes around the data. The data in the header is used for reliability, flow control, and more.
The width of the header in the figure below is 32 bits. In the first line, the source port runs from bits 0 to 15, and the destination port runs from bits 16 to 31. Then in the second line, the sequence number runs from bits 32 to 63. The header will always have the first five rows, giving it a minimum total length of 5 × 32 = 160 bits, which is 20 bytes. Options can take up further space.
The source and destination ports are both 16 bits, which means port numbers can run from 0 to 216–1, which is 0 to 65,535.
These, as we have seen, are used to keep the data in order as well as to know when segments have been lost. Sequence and ACK numbers are 32 bits, meaning they can run from 0 to 232–1, which is from 0 to a little over 4 billion.
Once we get to a sequence number at the max, the numbers will wrap back around to 0. This is not a problem except on very fast (gigabit) connections. We'll talk more about this below.
The initial sequence number is not typically 0 or 1, but rather it's an unpredictable value. This is for security, namely to make it harder for a remote attacker to inject data into a TCP connection. In order to inject data, an attacker needs to send data with a sequence number that falls inside the sliding window. Anything else will be ignored. If sequence numbers predictably started at 0, this would be considerably easier. Further, starting at 0 could mean that late-arriving packets from old connections could more easily interfere with the current connection.
If you use Wireshark, it might seem like sequence numbers are starting at 0, but Wireshark by default shows relative sequence numbers. A segment might in actuality have sequence number 2230398882, but Wireshark will show it as 2000 if it's the 2000th byte of the connection. There is an option to show the true sequence number, but it's usually easier to work with the relative number.
- SYN — This is used in the famous 3-way handshake in starting a connection. It is short for “synchronize sequence numbers”. It is never set except in the first two segments of the handshake.
- ACK — This flag is set in every TCP segment except for the initial SYN that starts a connection. Every other TCP segment will have an acknowledgement telling the other side what byte it's expecting next.
- FIN — This is used to end a connection. It's one side's way of telling the other that it is done sending data. Its only use is in closing a connection.
- RST — RST is short for “reset”. The RST flag is often set to indicate some sort of error. If a host receives a TCP segment that it wasn't expecting, it will often send a segment with RST set. For instance, if a server receives a SYN at port number where it is not expecting traffic, it often sends an RST in response to tell the other side to stop.
RSTs can also be used to abruptly end a connection. The proper way to end a connection is usually with FIN, but RST can be used as well. However, this can cause data loss as it means an immediate end to the connection. The Linux utility
tcpkilluses RSTs to stop TCP connections. - PSH — This is short for “push”. TCP connections are used by application layer programs. TCP, at the transport layer, handles the data transfer and sends the data up to the application layer. However, it doesn't send every byte up to the application as soon as it arrives. That wouldn't be very efficient. Instead it maintains a buffer (storage area) and sends the data up to the application once there's enough to be worth sending. However, sometimes the application should get the data right away. That's what the PSH flag was originally intended for, to tell the other side to send whatever is in the buffer immediately up to the application. This was useful for interactive programs, like Telnet.
However, it's not used much for that purpose anymore since those buffers are usually sent up to the application pretty quickly. You'll often see the PSH flag set by the sender on the last piece of data it has queued up to send, but, except for a few mostly uninteresting cases, the receiving side doesn't do much with that information.
- URG — This is short for “urgent”. It is very rarely used anymore. In fact, many firewalls automatically zero out the flag if it's set. It was originally meant to be used with the urgent pointer to indicate that a particular part of the data transmission contained urgent data. If the flag was set, the recipient was supposed to use the urgent pointer to go to a particular part of the data and do something about it.
The flags above are the original six in TCP. All but the last one are in very common use. Since the publication of the TCP specification in 1981, three more flags have been added: CWR, ECE, and AE, all of which are used for something called explicit congestion notification, which we won't get into here other than to say that it's used in concert with the network layer for routers to indicate to the endpoints of the connection that there is network congestion. Without it, the routers would typically drop the packets when they are congested.
Options are, as you might guess, optional extensions to TCP. We will cover a few of the most useful ones here.
- Window Scaling — As mentioned above, window sizes are limited to 65,535 bytes. If one side wants to use larger window sizes, they can use this option. It sets a scaling factor that tells what to multiply the window size value by. For instance, if the window size is 40,000 and the scaling factor is set to 3, then the actual window size will be 40,000 × 23 = 320,000 bytes. The scaling value always specifies which power of 2 to multiply by, from 20 to 214.
- Maximum Segment Size (MSS) — This allows one side to tell the other what the largest segment it can handle is. This tells the other side not to send it anything larger. Because much of the internet runs over Ethernet, which has a 1500-byte payload limitation, the MSS is usually a number in the 1400s, to leave space for headers, with 1460 being pretty common.
- SACK — SACK is short for Selective Acknowledgements. In standard TCP, if a sender sends segments 1, 2, 3, 4, 5, and Segment 3 is lost, the best the receiver can do is acknowledge Segments 1 and 2, even though they also got 4 and 5. The SACK option provides a way to acknowledge multiple separate ranges. The receiver could tell the sender that they got 1 and 2 as well as 4 and 5.
- Timestamp — Timestamps are used in many places in computer science to encode information about times and/or dates. The timestamp option in TCP allows a sender to mark a segment with a timestamp indicating when it was produced, based on counters that both parts of the connection maintain. Timestamps are useful in something called PAWS, Protection Against Wrapped Sequence Numbers. Recall that once the sequence numbers reach the limit of 232–1 (around 4 billion), they wrap back around to 0. On a 1-gigabit connection, this wraparound can take 232 · 8/109 ≈ 34 seconds. On a 10-gigabit connection it can take only 3.4 seconds. Sometimes packets get stuck on the internet and don't arrive until several seconds later. An segment could arrive late enough that the sequence numbers have already wrapped around, and it could be confused for a newer segment. Timestamps are used to help with this. If a segment's timestamp looks too much older compared to other recent timestamps, it is discarded.
- NOP — This is short for “no operation”. It's not really an option. Instead it's used for padding, specifically so the options line up nicely in the 32-bit rows of the TCP header.
Application layer protocols and TCP/UDP
Each application layer protocol needs to use a transport layer protocol, which is almost always either TCP or UDP. As a general rule, if TCP is useful when we need reliability, while UDP is useful if we value speed over reliability and for short messages where the overhead of setting up a TCP connection is not worth it. A good example is DNS, which uses UDP for most simple queries. Each query is essentially just a quick question that usually has a single short answer. If the response gets lost, DNS will just retry the query itself or possibly try a different DNS server. On the other hand, DNS zone transfers use TCP. Zone transfers are where we copy all the records for a DNS zone to a different server. This involves a lot more data than a simple DNS query, and we need the reliability that TCP provides in this case.
TCP is used for SSH, SFTP, SMTP, IMAP, POP, Telnet, and FTP, all of which often involve either long-running connections or data transfer that needs reliability. UDP is used for simple DNS queries, NTP, and DHCP (covered later), all of which involve simple queries with short responses. Zoom typically uses UDP for the audio/video feed and TCP for chat messages.
A particularly interesting case is HTTP. HTTP/1.1 and HTTP/2.0, as well as HTTPS over those, use TCP. However, HTTP/3 uses UDP. Downloading web pages and resources often involve long-running connections and a lot of data, so reliability is highly desirable. So why does HTTP/3 use UDP? It uses a protocol called QUIC that runs over UDP but adds its own reliability, flow control, and congestion control on top of UDP. QUIC was initially developed at Google and became an internet standard that is closely intertwined with HTTP/3. It uses many of the same mechanisms that TCP uses for reliability, flow control, and congestion control, but updated for the modern internet. TCP was developed starting in the late 1970s, and the internet has changed considerably since then.